K-Medoids and K-Means Clustering in High School Teacher Distribution
ICEEIE 2019 - International Conference on Electrical, Electronics and Information Engineering: Emerging Innovative Technology for Sustainable Future · 2019
Summary
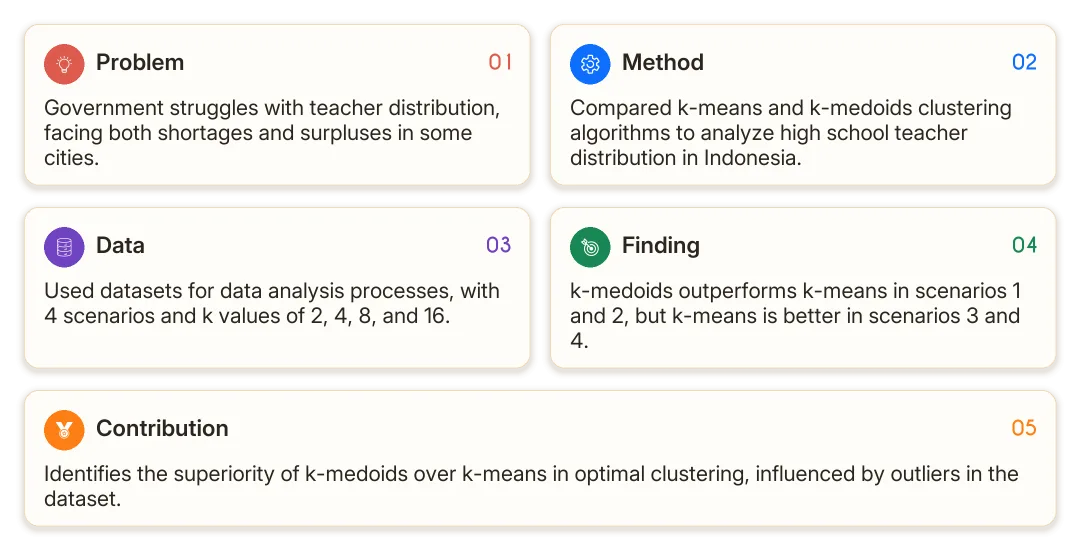
In optimal clustering, k-medoids outperforms k-means clustering due to the influence of outliers in the dataset.
Details
Abstract
Today, the government still has difficulties in distributing teachers. The problem is not just a shortage teachers but also an excess teachers in several cities. In data mining clustering is useful for obtaining the distribution patterns of datasets used for data analysis processes. The purpose of this research is to compare k-means and k-medoids clustering algorithm to analyze distribution of high school teachers in Indonesia. This research uses four steps, namely dataset selection, preprocessing data, implementation, and evaluation with 4 scenarios with k = 2, 4, 8, and 16. The test results obtained Sum of Squared Error (SSE) of k-medoids is better than k-means for scenario 1 and scenario 2. In contrast to scenario 3 and scenario 4, k-means better than k-medoids. The optimal cluster test results with the Silhouette width obtained at k = 2. It can be concluded that in optimal clustering, k-medoids is better than k-means clustering. This is due to the influence of the outlier on the dataset. © 2019 IEEE.
Affiliations
Universitas Negeri Malang, Electrical Engineering Department, Malang, Indonesia